What is Text-to-video?
Generating a short video clip from a written description — the technology behind Veo, Sora and Kling.
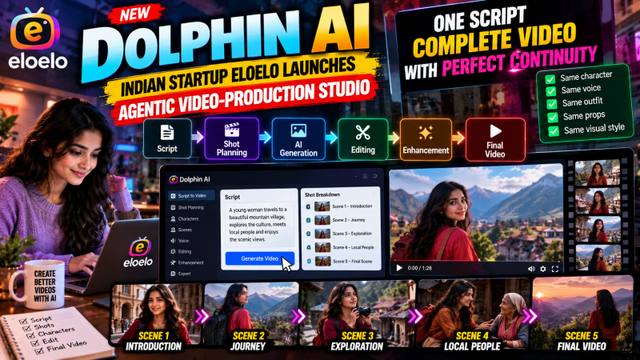
Text-to-video models create moving scenes, camera motion and (in newer models) sound from a prompt. Clips are usually a few seconds long and are stitched together for reels and ads.
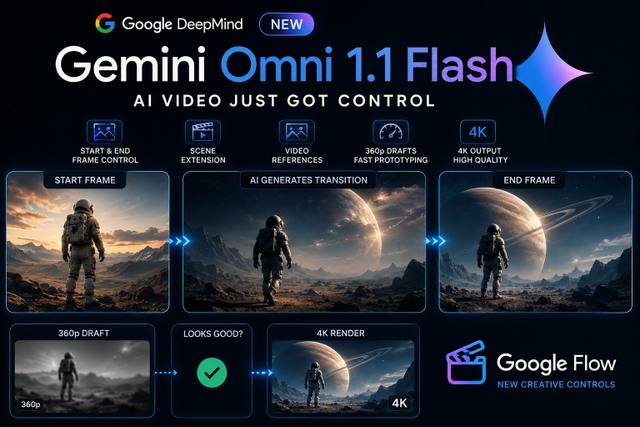
Video prompts work best when they describe the shot like a director: subject, action, camera movement (dolly in, slow pan, drone shot), lighting and mood, plus how the clip should start and end.
Director-style prompt
“Slow dolly-in on a chai seller pouring tea at a Mumbai street stall during monsoon rain, steam rising, warm tungsten light, shallow depth of field, 8 seconds.”
Related terms
Creating a picture from a written description. The core feature of ChatGPT images, Gemini, Midjourney and Flux.
The main technology behind AI images and video: the model starts from random noise and gradually refines it into a picture that matches your prompt.
The width-to-height shape of an image or video, like 9:16 for reels, 4:5 for Instagram posts or 16:9 for YouTube.