What is Multimodal AI?
AI that understands and produces more than one kind of input — text, images, audio and video — in the same conversation.
Early chatbots only handled text. Multimodal models can look at a photo, listen to your voice, read a chart in a PDF and reply with text, an edited image or speech.
This is what makes features like “upload your selfie and turn it into a festive portrait” or “take a photo of this maths problem and explain it” possible.
For creators, multimodal tools remove a lot of busywork: you can show the AI a reference photo instead of describing it, ask it to read a screenshot of analytics, or speak your idea aloud while driving. The results are only as good as the input, so share clear, well-lit images and say exactly what you want changed.
Try it
Upload a photo of your room and ask: “Suggest three low-budget ways to make this study corner brighter, and mark them on the image.”
Related terms
AI that creates new content — text, images, audio, video or code — instead of only sorting or analysing existing data.
Giving the AI an existing photo plus instructions, so it transforms that image instead of starting from nothing.
The type of AI behind chatbots like ChatGPT, Gemini and Claude, trained on huge amounts of text to predict and generate language.
In the news
 AI Model Fatigue Is Here: Too Many Models, Too Little TimeOct 2, 2026
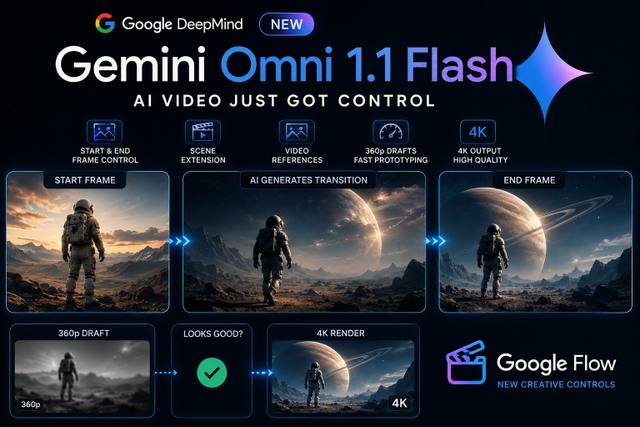 Gemini Omni 1.1 Flash Gives AI Video More ControlOct 2, 2026
 How to Turn a Rakhi Photo into a Heartwarming Video with AIAug 24, 2026
 Google Launches Gemini 3.7 Flash: New AI Model for Coding, AI Agents and Complex WorkflowsAug 14, 2026