Claude Prompt Caching Failure: The Hidden AI Cost Trap
A developer's investigation found that Claude prompt caching worked at nearly 488K tokens but stopped producing cache reads in tests above 732K tokens.
By @admin
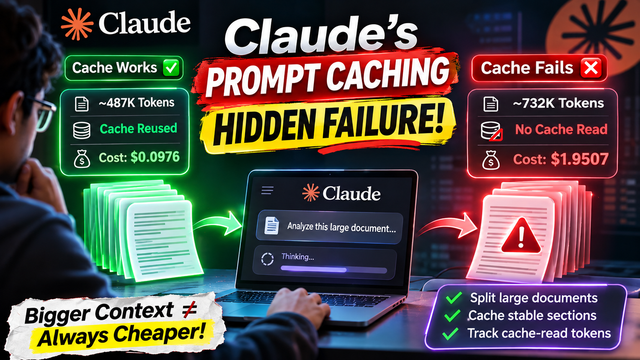
Claude Prompt Caching Failure: The Hidden AI Cost Trap Developers Should Know About
Imagine sending a 500,000-token document to an AI model.
You ask Claude to analyze it. Then you ask another question about the same document.
You expect the second request to be cheaper because the model has already processed the information.
But what if the AI still remembers the document while your API bill suddenly increases?
That is exactly the unusual behaviour highlighted in a September 4, 2026 investigation by developer and AI researcher Mervin Praison.
His experiment revealed an important distinction between two things developers often confuse: an AI model being able to process information and an API successfully reusing cached information.
The investigation found that Claude's prompt caching worked at nearly 488,000 tokens but stopped producing cache reads in tests at larger context sizes.
There was no obvious error message warning that the discount had disappeared.
For developers building AI agents, research assistants and applications that process enormous documents, this is an important finding.
Let's understand what happened.
1. First, what exactly is prompt caching?
Before looking at the experiment, we need to understand prompt caching.
Whenever you send a request to an AI model, the system processes input tokens.
These tokens represent the information you provide, including:
- System instructions.
- User messages.
- Uploaded documents.
- Code files.
- Conversation context.
- Tool definitions and other supporting information.
Imagine building an AI assistant for a company.
Every time an employee asks a question, your application sends the same 100-page company handbook along with the new question.
Without caching, the model may need to process that repeated context again and again.
That creates unnecessary processing costs.
Prompt caching addresses this problem.
Instead of repeatedly paying the full input price for identical content, the system can reuse previously cached context when the request matches the cached prefix and the cache remains valid.
For example:
First request:
Company handbook + Question 1.
Second request:
Same company handbook + Question 2.
If the cache is reused successfully, the repeated document can be charged at a significantly lower cache-read rate.
Anthropic has advertised prompt caching savings of up to 90% on eligible cached input tokens, depending on the applicable model and pricing.
In simple words:
Send the same information repeatedly, and caching can make those repeated requests much cheaper.
But there is an important condition: the system must actually register a cache hit.
2. Mervin Praison's experiment: What happened?
On September 4, 2026, Mervin Praison published an investigation titled:
"Claude's Prompt Cache Stops Working Somewhere Past 500K Tokens."
He conducted experiments using Claude Sonnet 5 through Claude Code CLI.
His approach was straightforward.
He generated large documents, sent them to Claude and repeated the same request with identical context.
He then compared the token usage and cost between the first and second requests.
The results were surprising.
At approximately 244,177 tokens, caching worked.
At 487,651 tokens, caching still worked.
However, when the document size increased to 732,942 tokens, the second request showed zero cache-read tokens.
He repeated the tests and observed the same behaviour.
His investigation also reported zero cache reads at 976,433 tokens.
Here is the important comparison:
Input tokens| Cache behaviour
244,177| Full cache reuse
487,651| Full cache reuse
732,942| Zero cache reads
976,433| Zero cache reads
These numbers came from his particular test environment.
The exact point where caching stopped working was not identified. The results only established that it worked at 487,651 tokens and failed at the larger tested sizes.
That is why developers should treat this as an observed issue requiring independent verification, not a guaranteed 500K-token limit.
3. The 20x cost difference
One of the most interesting parts of the investigation was the actual cost comparison.
At 487,651 input tokens, the second request reportedly cost approximately $0.0976.
Without the cache discount, the equivalent request would have cost approximately $1.9507.
That is roughly a 20x difference.
Now imagine running an AI application that repeatedly processes massive documents.
A small difference in per-request costs can become significant when your application handles thousands or millions of requests.
For example, consider a research assistant that processes large technical documents.
Users might repeatedly ask:
- Summarize this document.
- Find a specific technical detail.
- Compare two sections.
- Identify contradictions.
- Generate a report.
If the stable context is successfully cached, repeated requests can become considerably cheaper.
But if caching silently stops working, your application may continue operating normally while your infrastructure expenses increase.
That is the real concern.
4. Is Claude forgetting the document?
Here comes the most interesting part.
Mervin Praison wanted to determine whether the issue was related to the model's ability to process extremely large documents.
So he conducted additional retrieval tests.
He placed specific facts at different positions inside large documents and asked Claude to retrieve them.
The results were:
- Short and long document tests: 60/60 correct.
- Multiple-fact retrieval tests: 10/10 correct.
- Baseline tests: 5/5 correct.
- Extreme context tests at approximately 976K tokens: 15/15 correct.
Overall, his investigation reported 90 correct retrievals out of 90 attempts.
This suggests that the model could still retrieve the tested information at the larger context sizes where cache reads were failing.
However, 90/90 retrievals do not prove perfect comprehension of every document or every task.
The important distinction is that the experiment observed a caching problem, not an equivalent failure of factual retrieval.
Think about it this way:
You give someone a 1,000-page book.
They can still find a specific sentence when you ask a question.
But every time you ask another question, they may have to pay to process the entire book again.
The information is accessible, but the cost-saving mechanism is not working.
That is the difference between context processing and cache reuse.
5. Why does this matter for AI developers?
This investigation matters particularly for developers building applications with large context windows.
Consider these examples.
AI coding agents
A coding agent may repeatedly process an entire repository, including source files, documentation and system instructions.
Caching stable context can reduce repeated processing costs.
AI research assistants
Research applications may work with hundreds of documents, scientific papers and technical reports.
If the same documents are repeatedly included in requests, caching becomes valuable.
Enterprise AI assistants
Businesses may use large internal knowledge bases containing policies, manuals and operational documentation.
A failure to reuse cached context can increase the cost of handling employee queries.
AI automation platforms
Agents frequently reuse system prompts, tool definitions and workflow instructions.
Developers should understand which parts of the request remain stable and which parts change.
In all these situations, assuming that repeated input automatically means discounted input is a mistake.
6. How developers can reduce unnecessary AI costs
Mervin Praison suggested several practical approaches for developers working with extremely large contexts.
Here are the most useful ones.
A. Split extremely large documents
Instead of placing an enormous document into one request, divide it into smaller logical sections.
For example:
- Document 1: Introduction and overview.
- Document 2: Technical specifications.
- Document 3: Research findings.
- Document 4: Supporting references.
Then retrieve only the sections relevant to the user's question.
This can reduce unnecessary repeated context.
However, splitting alone does not guarantee cache hits. Each segment must still be eligible for caching and reused correctly.
B. Cache stable sections
Keep frequently reused information separate from changing information.
For example:
Stable context:
- System instructions.
- Company documentation.
- Tool definitions.
- Reusable reference material.
Dynamic context:
- User's latest question.
- Current date.
- New conversation details.
- Changing variables.
Structure your requests so the stable prefix can be reused.
C. Monitor cache-read tokens
This is probably the most important recommendation.
Do not measure your AI application's efficiency using the total API bill alone.
Inspect the usage information returned by the API.
Two important fields are:
"cache_creation_input_tokens"
and
"cache_read_input_tokens"
The first indicates how many input tokens were written into the cache.
The second indicates how many input tokens were successfully read from the cache.
If you expect cache reuse but the cache-read value is zero, investigate the request.
D. Track the cost of individual requests
Build a simple monitoring system that records:
- Total input tokens.
- Cache creation tokens.
- Cache read tokens.
- Output tokens.
- Request latency.
- Estimated request cost.
This will help you identify unexpected cost increases before they become a major problem.
E. Test your own environment
One important limitation of Praison's investigation is that his tests were conducted through Claude Code CLI.
He explicitly stated that he did not verify the same behaviour using the raw Anthropic Messages API.
Therefore, developers using the raw API, SDKs or different integrations should test their own workloads before assuming the same behaviour applies.
7. What does Anthropic's official documentation say?
Anthropic's official documentation explains that prompt caching uses cache breakpoints and matching prompt prefixes.
The system can reuse cached content when the relevant prefix remains identical and the cache entry is still available.
It also explains that the default cache lifetime is five minutes, with an optional one-hour cache duration.
This means caching is not simply a feature that remembers everything indefinitely.
Developers must understand how cache breakpoints, request structure, model compatibility and cache expiration work.
The official documentation also provides guidance on checking cache performance through token usage information.
Importantly, Praison's investigation did not establish that Anthropic officially recognizes a universal maximum cache size of 500K tokens.
His results are a valuable independent observation, but they should not be confused with an official platform limitation.
8. The bigger lesson: Bigger context does not always mean cheaper AI
AI models are increasingly capable of processing enormous amounts of information.
But larger context windows introduce another challenge.
The more information your application sends, the more important it becomes to manage that information efficiently.
Developers need to think beyond model intelligence and focus on infrastructure economics.
A powerful model that answers questions accurately can still become expensive if your application repeatedly sends large amounts of unnecessary input.
The goal should not simply be to send more tokens.
The goal should be to send the right information, reuse stable context and measure actual resource consumption.
For companies operating AI applications at scale, this difference can have a direct impact on profitability.
Final thoughts
Mervin Praison's investigation highlights an important lesson for anyone building serious applications with Claude.
Prompt caching can significantly reduce costs, but developers should never assume that a repeated request automatically receives the expected discount.
Measure cache reads.
Separate stable and dynamic context.
Split extremely large documents when appropriate.
And test the behaviour against your actual model and API integration.
The most expensive part of an AI application might not be the model itself.
It might be the unnecessary tokens your application keeps sending.
Remember: A bigger context window does not automatically mean a cheaper AI workflow.
Do you currently monitor cache-read tokens in your AI applications, or do you only check the total API bill?
Share your experience in the comments.